Theo Lepage

I'm Theo Lepage. I hold a Ph.D. in Artificial Intelligence from Sorbonne University and my research focuses on AI/ML for Speech, notably speaker recognition and speech anti-spoofing, with a broader interest in self-supervised learning. Through my work, I aim to develop technologies capable of interpreting all aspects of human conversations.
Read my resume
Send me an email
Alternatively, you can explore my profiles on:
icon-githubicon-scholaricon-linkedinicon-twitter

Research

My Ph.D. thesis focused on self-supervised speaker verification, with the objective of reaching supervised performance while reducing reliance on labeled data. The main contributions were SSPS → a novel latent-space positive sampling (-58% EER for SimCLR), and DINO-WavLM → an iterative pseudo-labeling approach to leverage WavLM without speaker labels (1.06% EER on VoxCeleb1-O). This research is open-sourced as sslsv, a PyTorch toolkit for self-supervised speaker verification.

I am also interested in speech anti-spoofing and deepfake detection. Our WavLM-based countermeasure, submitted at the ASVspoof 2024 challenge, placed 3rd (Track 1, Open).

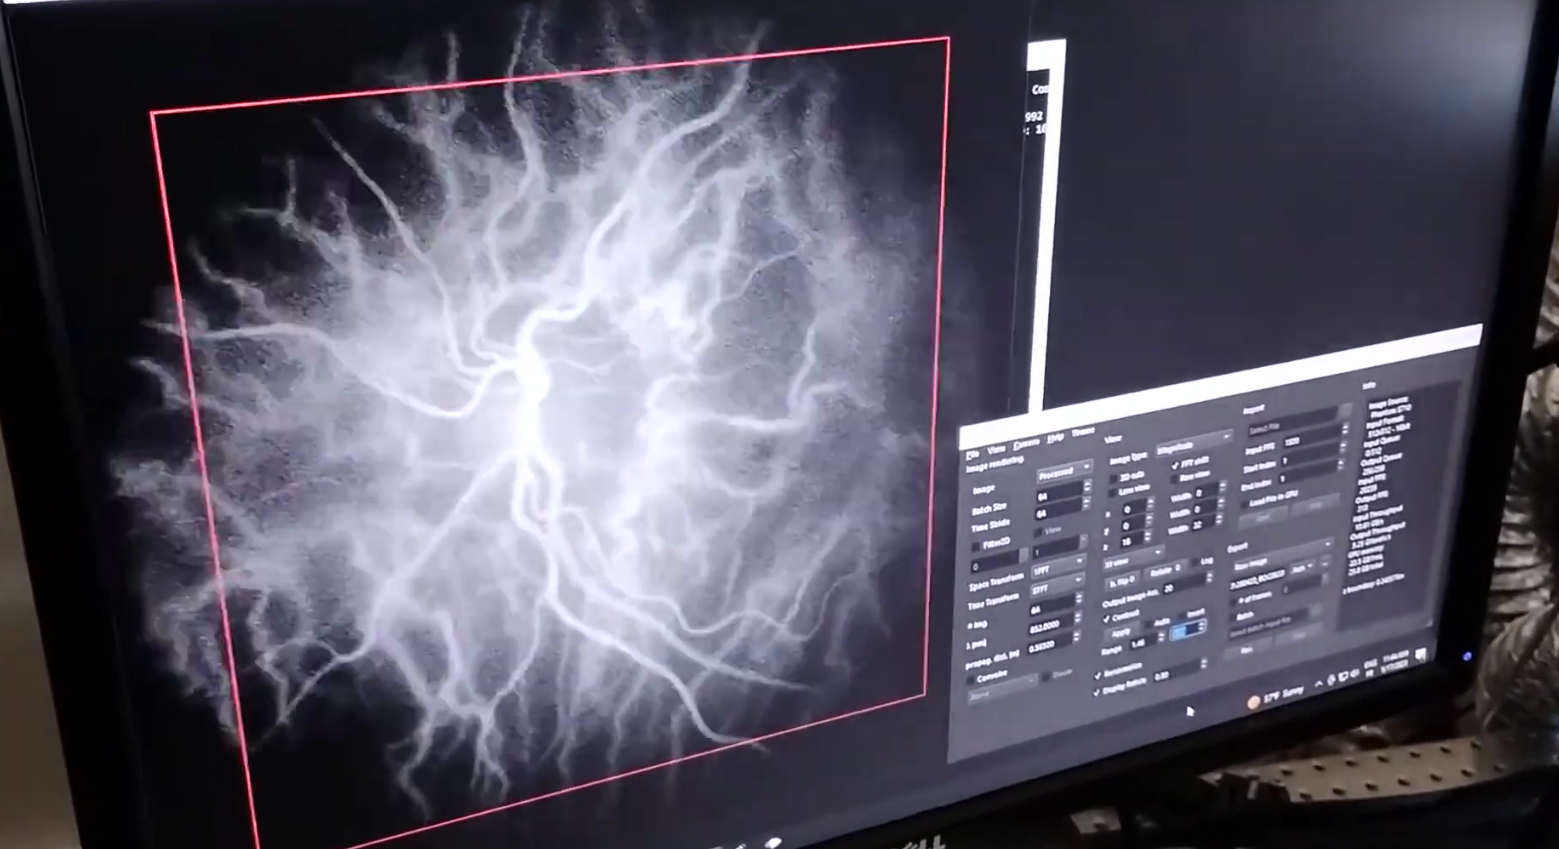
Earlier, I worked on computer vision for medical imaging: MR image enhancement at Siemens Healthineers and real-time digital holography for retinal blood flow analysis at CNRS.

Experience
EPITA Research Laboratory (LRE) logo
Paris, FranceNov. 2022 - May. 2026

Proposed self-supervised methods for speaker recognition • Published 8 papers at top venues (Interspeech, IEEE TASLP, Speech Communication) • DINO-WavLM → SOTA performance on VoxCeleb (1.06% EER on Vox1-O) • SSPS → latent-space positive sampling (-58% EER for SimCLR) • sslsv → open-source PyTorch toolkit for self-supervised speaker verification
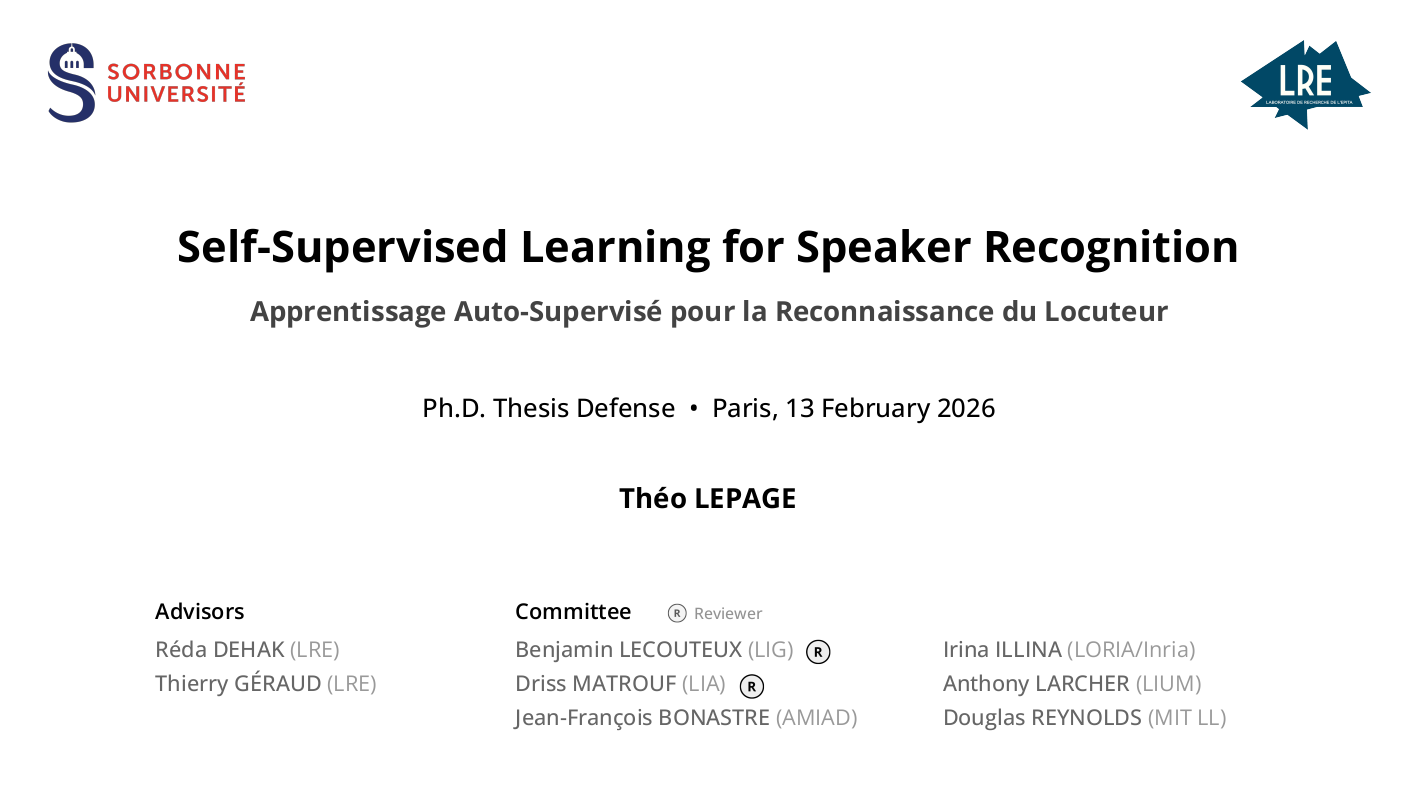
Self-Supervised Learning for Speaker Recognition (Ph.D. Thesis)
Siemens Healthineers logo
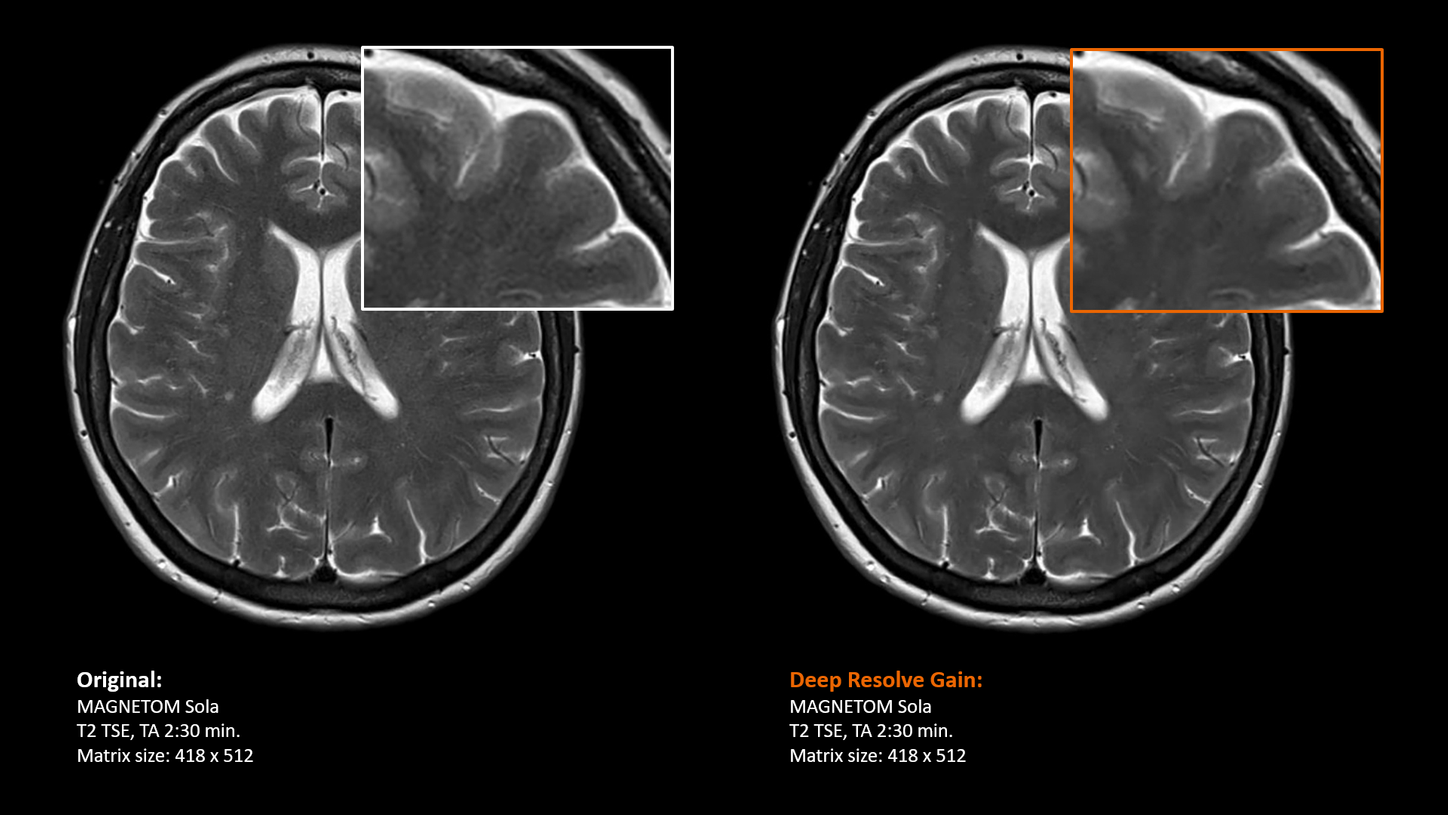
Research Scientist (Internship) at Siemens Healthineers
Princeton, USAFeb. 2022 - Sep. 2022

Developed deep learning models (CNN with self-attention) for end-to-end MR image enhancement (denoising & super-resolution)
CNRS logo
Software Engineer (Internship) at CNRS
Paris, FranceSep. 2020 - Jan. 2021

Contributed to Holovibes, real-time digital holography software for retinal blood flow analysis → 20× input throughput (10,000 FPS)
Education

Sorbonne Université logo
Sorbonne Université (Ph.D. in Artificial Intelligence)
Paris, FranceNov. 2022 - Feb. 2026

Thesis: Self-Supervised Learning for Speaker Recognition • Supervised by Reda Dehak @ LRE-EPITA • Proposed self-supervised methods for speaker verification • Published 8 papers at top venues (Interspeech, IEEE TASLP, Speech Communication)
École Pour l'Informatique et les Techniques Avancées - EPITA logo
Paris, FranceSep. 2017 - Sep. 2022GPA: 3.9/4.0

Major: AI/ML for Computer Vision • Research student • Teaching assistant (C & Unix) • Exchange semester at CSUMB

Publications

Preview
Self-Supervised Learning for Speaker Recognition: A study and review
2026
Speech Communication
Theo Lepage and Reda Dehak
Article
/
Code
/
Preview
SSPS: Self-Supervised Positive Sampling for Robust Self-Supervised Speaker Verification
2025
Interspeech 2025
Theo Lepage and Reda Dehak
Preview
Self-Supervised Frameworks for Speaker Verification via Bootstrapped Positive Sampling
2025
IEEE Transactions on Audio, Speech and Language Processing
Theo Lepage and Reda Dehak
See all publications

Projects

speakerscope.ai preview
speakerscope.ai
speakerscope.ai
Speaker diarization with identity and language insights, via browser or API, powered by SOTA AI speech models.
sslsv preview
sslsv
sslsv
41
9
Toolkit for training and evaluating Self-Supervised Learning (SSL) frameworks for Speaker Verification (SV).
wavlm_ssl_sv preview
wavlm_ssl_sv
wavlm_ssl_sv
8
0
SOTA method for self-supervised speaker verification leveraging a large-scale pretrained ASR model.
See all projects

Talks

Self-Supervised Learning for Speaker Recognition (Ph.D. Thesis Defense)
Feb. 2026
EPITA — Paris, France
SSPS: Self-Supervised Positive Sampling for Robust Self-Supervised Speaker Verification
Aug. 2025
Interspeech 2025 — Rotterdam, The Netherlands
Self-Supervised Learning for Speaker Recognition
Mar. 2025
Inria — Paris, France
See all talks

Teaching

Introduction to Deep Neural Networks
Spring 2023 - 2025 @ EPITA
Python for Data Science
Spring 2023 - 2025 @ EPITA
Rust Programming
Spring 2020 @ EPITA
Unix / C Programming
Fall 2019 @ EPITA

Miscellaneous

Academic Service
Reviewer for Interspeech & ICASSP
Awards & Honors
3rd place @ ASVspoof 5 (Track 1)
© 2026 Theo Lepage